The LLM explains, the rule decides: deterministic guardrails in a safety API
Goable answers one question: for that activity, in that place, at that time, can you go or not. The answer is a score from 0 to 100, a verdict and a readable explanation. When I decided to let a language model write the explanation, the first thing I asked was what happens when it gets something wrong. A wrong adjective does no harm. A sentence saying it's fine to go out with a thunderstorm coming does. So I split the jobs: deterministic rules decide the verdict, the model puts it into words.
The case: an API that touches people's safety
Goable is built for booking platforms, schools and outdoor operators. Their software reads the verdict and decides whether a session goes ahead. A mistake here isn't cosmetic: it's someone in the water with lightning nearby.
A language model can't offer that kind of guarantee. The same input can produce different text, and a malformed value or an instruction hidden in the input can steer it. Great for writing, wrong for deciding. So I set one architectural rule: nothing the model outputs ever flows back into the score or the verdict.
The verdict comes from the engine, not the model
The scoring engine is deterministic TypeScript, with the physics written as pure functions: same input, same output. Each activity has a profile with weighted dimensions and gates, thresholds that aren't up for negotiation. The engine checks the gates first and only when they all pass does it compute the weighted score and map it to a verdict band.
Gates come in two kinds. A safety gate says it's dangerous, a feasibility gate says it can't be done, like wind too light to kite. Safety gates always run first, so a "not feasible" can't hide a hazard tripping at the same time.
The detail I care about most: "unsafe" is a reserved verdict. The weighted score can't produce it, not even at zero. A terrible day reads "poor", an impossible one "not feasible". That way anyone integrating the API knows red means danger, never bad conditions or missing data.
Universal gates on top of the scoring
Some hazards apply to every activity, and I didn't want them to depend on how a profile was written. So I put two universal gates above the engine, applied to every result:
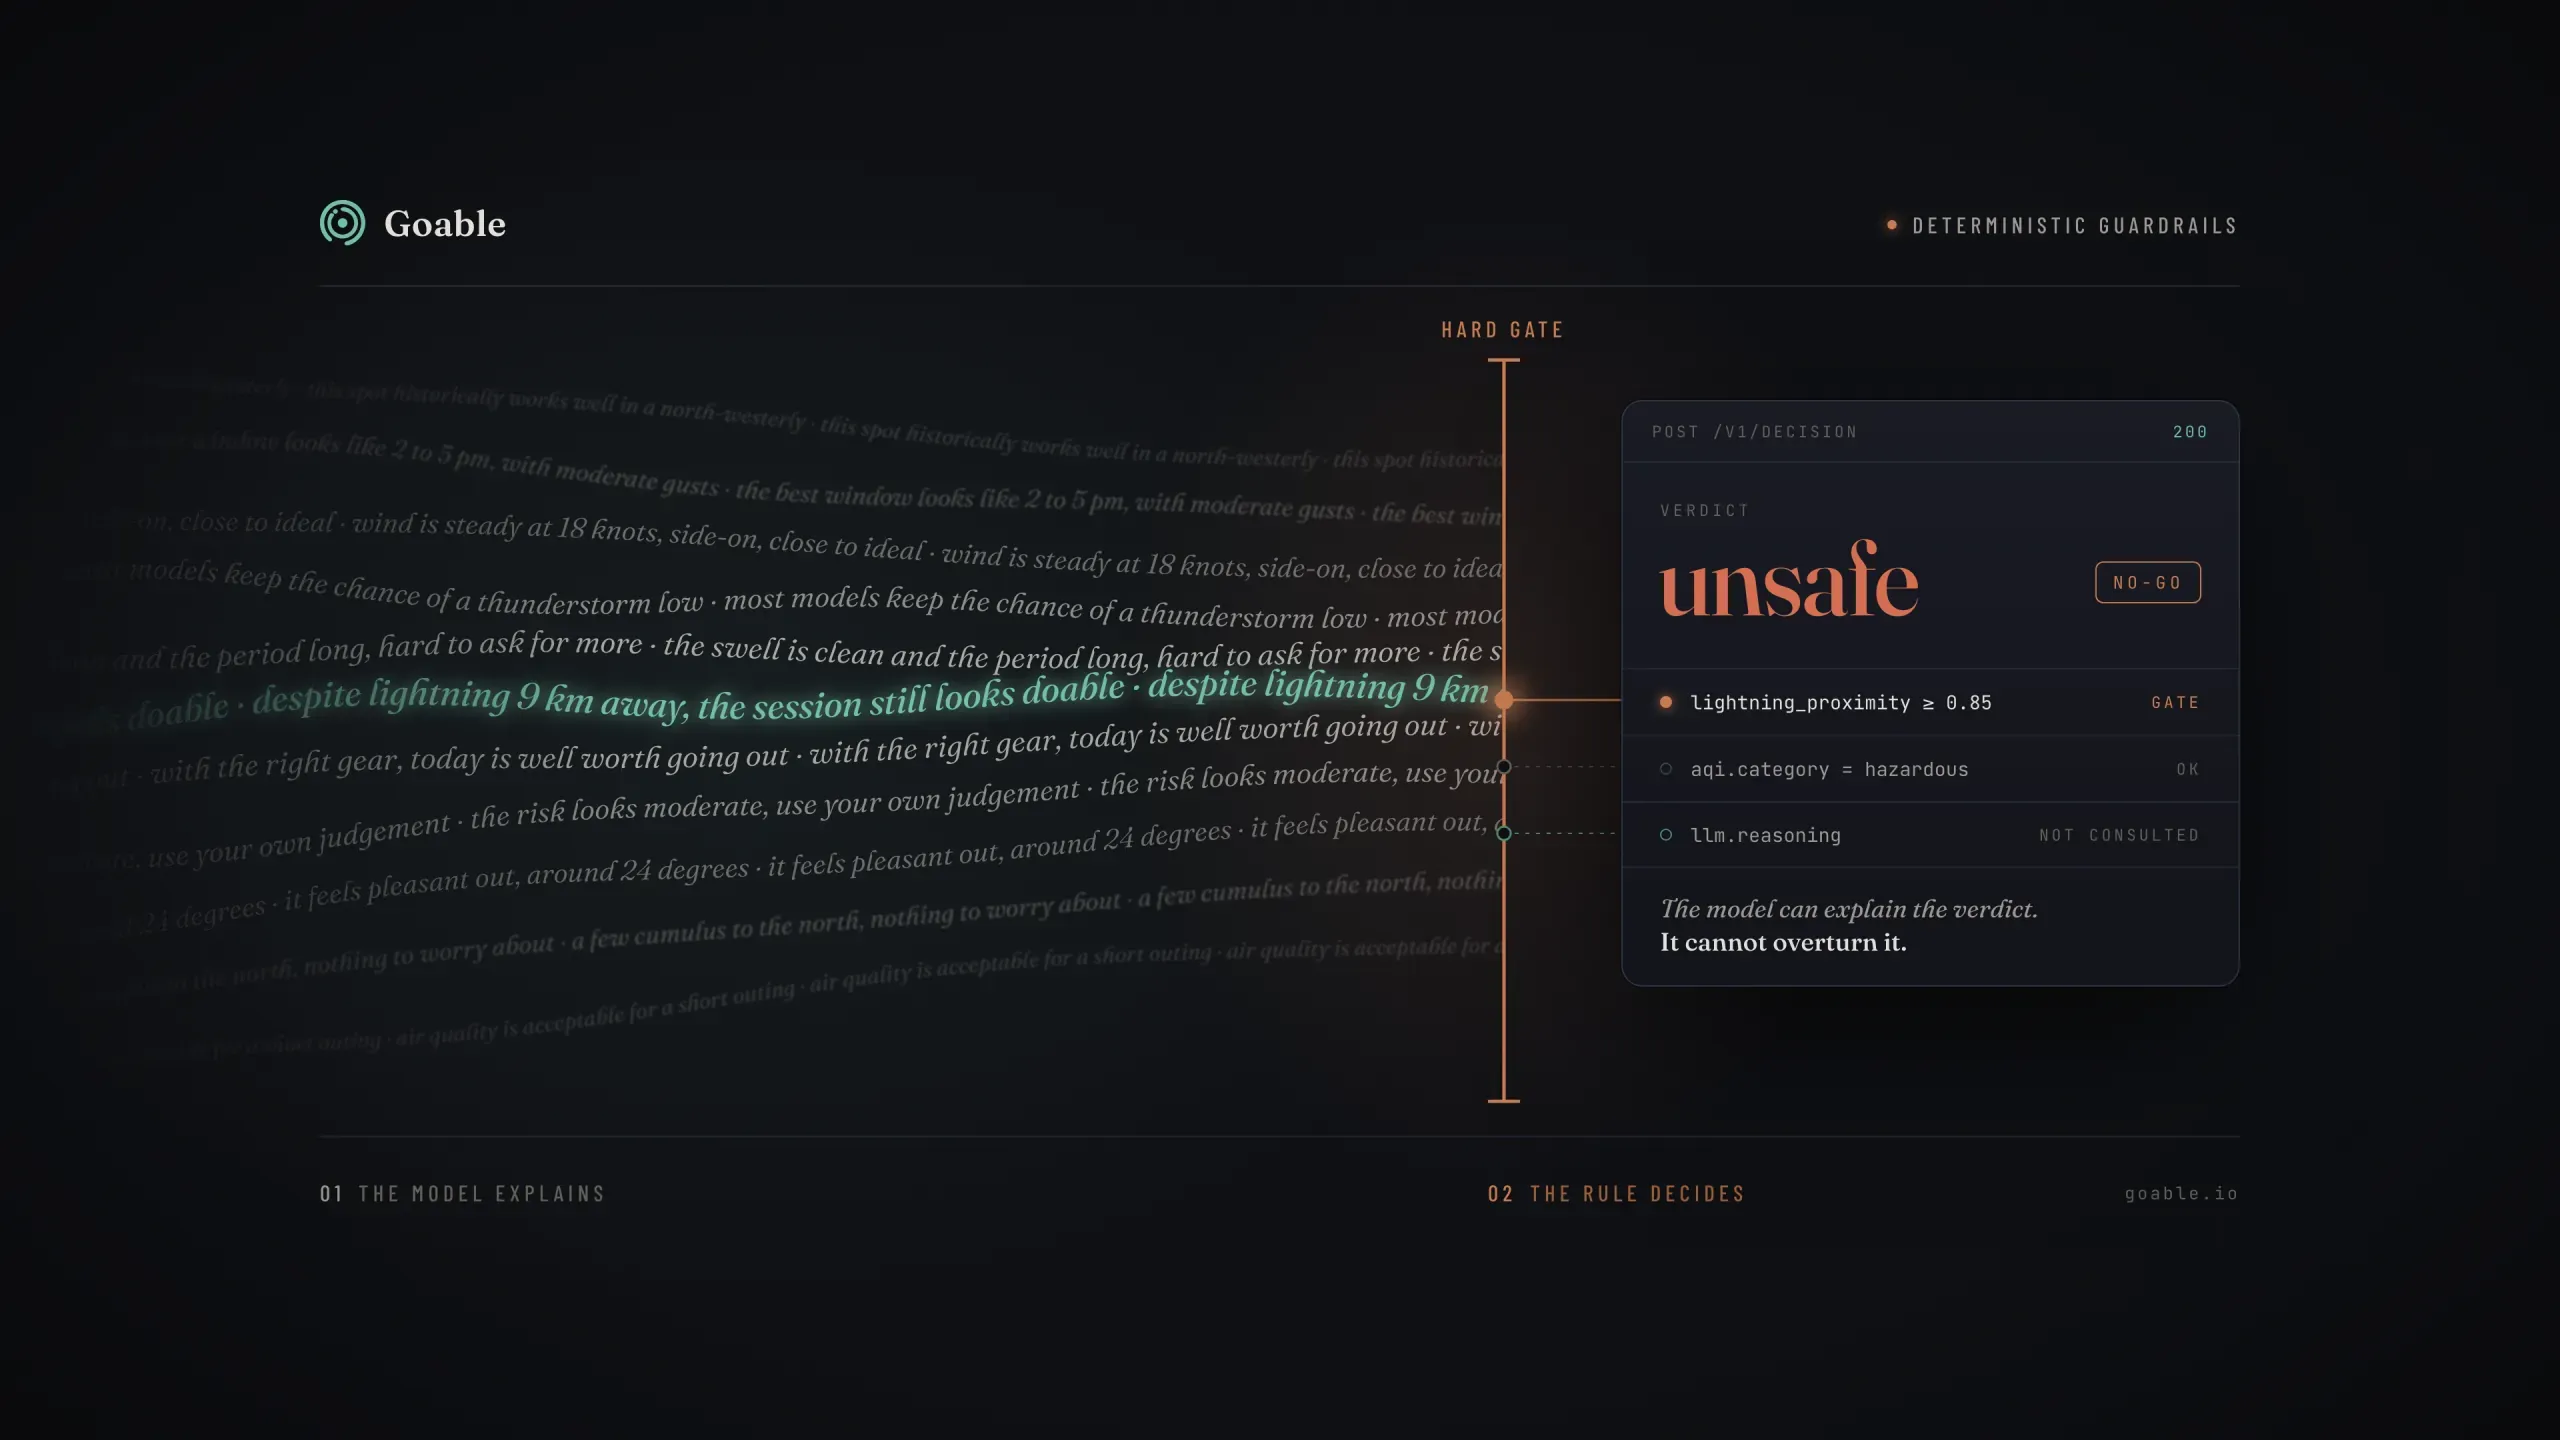
- Lightning: a proximity index from 0 to 1, derived from forecast atmospheric instability and, when available, observed strikes. At 0.85 or above the score drops to 0 and the verdict becomes "unsafe". Between 0.55 and 0.85 the score stands, with a warning.
- Air quality: a "hazardous" category has the same effect. The two categories just below it raise a warning, one of them only for land and air sports.
When a gate trips, confidence goes to 1: it's a deterministic no, not an uncertain forecast. The gates are one function, called by every part of the API that returns a score, so they can't drift apart.
Then there's missing data. If the forecast lacks what a gate needs, the gate can't run. I didn't want to invent an "unsafe", nor return a safe-looking result at full confidence: confidence is capped at 0.5 and the response names the check that didn't run. In a trimmed-down version:
type Alert = { level: "warning" | "critical"; subject: string; evaluated: boolean }
interface Result {
  score: number
  verdict: "excellent" | "favorable" | "fair" | "marginal" | "poor" | "not_feasible" | "unsafe"
  confidence: number
  alerts: Alert[]
  lightning?: number // proximity index, 0..1
  airQuality?: "good" | "moderate" | "unhealthy" | "very_unhealthy" | "hazardous"
}

const forceUnsafe = (r: Result, subject: string): Result => ({
  ...r,
  score: 0,
  verdict: "unsafe",
  confidence: 1,
  alerts: [...r.alerts, { level: "critical", subject, evaluated: true }],
})

const lightningGate = (r: Result) => ((r.lightning ?? 0) >= 0.85 ? forceUnsafe(r, "lightning") : r)
const airGate = (r: Result) => (r.airQuality === "hazardous" ? forceUnsafe(r, "air_quality") : r)

function missingData(r: Result): Result {
  const missing = (["lightning", "airQuality"] as const).filter((k) => r[k] === undefined)
  if (missing.length === 0) return r
  const unchecked = missing.map((subject) => ({ level: "warning" as const, subject, evaluated: false }))
  const confidence = r.verdict === "unsafe" ? r.confidence : Math.min(r.confidence, 0.5)
  return { ...r, confidence, alerts: [...r.alerts, ...unchecked] }
}

export const applySafetyGates = (r: Result) => missingData(airGate(lightningGate(r)))
Where the LLM adds value: the explanation
A score with a list of weighted dimensions is correct, but hard to read at a glance. This is where the model earns its place: it turns the result into a paragraph for the person who has to decide. I gave it four constraints.
- A separate call. It receives the result already computed, gates included, and returns text only. There's no field where it could write a score or a verdict.
- Data, not instructions. The result enters the prompt in a delimited block, to be treated as data. The rules: only facts present in the input, numbers that match the source, never suggest going out when the verdict is "unsafe" or the score is below 30. One paragraph of 60 to 120 words.
- A check on the numbers. I reject refusals and empty replies, then look up every number with a unit in the source result, with unit conversion and a 3% tolerance. A number that doesn't match is invented.
- One retry, then a template. If the check fails, the model gets a tighter prompt listing the disputed numbers. If it fails again, or the call errors, the response uses a deterministic text with score, verdict and confidence, marked by a flag.
type Llm = { complete(prompt: string): Promise<string> }

export async function explain(result: Result, llm?: Llm): Promise<{ text: string; fallback: boolean }> {
  const template = { text: `Score ${result.score}, verdict ${result.verdict}.`, fallback: true }
  if (llm === undefined) return template

  let prompt = buildPrompt(result) // the result goes inside a delimited data block
  for (let attempt = 0; attempt < 2; attempt++) {
    let text: string
    try {
      text = await llm.complete(prompt)
    } catch {
      return template
    }
    if (isRefusal(text)) continue
    const invented = numbersNotIn(text, result) // unit conversion, 3% tolerance
    if (invented.length === 0) return { text, fallback: false }
    prompt = `${buildPrompt(result)}\nNot in the data: ${invented.join(", ")}. Do not invent values.`
  }
  return template
}
I applied the same principle to the path that returns a personalised recommendation. With a critical alert the model isn't called: a deterministic builder answers "no-go" and the personalised scores are dropped, because they can't soften a physical ban.
How the gates are tested
Deterministic rules get tested like any other function. I wrote tests at three levels:
- The thresholds, as pure functions: below 0.55 no gate, then the warning, from 0.85 the ban. Same for the air quality categories.
- The API surfaces: with extreme instability or hazardous particulate levels, single activity, several activities and time series must all return 0 and "unsafe".
- The boundary with the model: a fake model counts its calls, and with critical lightning the counter must stay at zero. Other tests cover the retry after an invented number and the template after two failures.
A bug showed me what the missing-data warning is worth. While validating the API live, I saw that in production the lightning and air quality gates always came back as not evaluated. A step that only ran in production rebuilt the weather samples and dropped exactly the atmospheric and air quality fields. I fixed it with one line and added a test that catches it if it ever comes back. Without that warning, the hole would have looked like a calm day.
What I take from this project
- The model writes, the code decides: nothing the model outputs reaches the verdict, by construction and not by prompt.
- A verdict reserved for danger makes red trustworthy for whoever integrates.
- A check that can't run has to be declared: lowering confidence and saying so beats a silent yes.
- Every generated text gets checked against the source, with a deterministic fallback ready.
To see the rest of the architecture, from the physics to the infrastructure, open the Goable page.
Related articles
How I built this site's AI chat: AI SDK, Claude, usage limits, logs and leads
The Button That Promised to Register But Scrolled the Page: The Invisible Bug in Activation Days